Have you ever wondered how Netflix always seems to know exactly what movie or TV show to recommend next? The secret lies in machine learning. By analyzing your viewing history, ratings, and even the habits of viewers with similar tastes, Netflix’s algorithms detect patterns and predict which content you might enjoy. It’s not just random suggestions, it’s a sophisticated system that processes vast amounts of data to tailor recommendations for you, ensuring that your next binge-watching session feels perfectly curated just for you.
But what is machine learning? Machine learning is a branch of artificial intelligence that enables computers to learn from data and make predictions or decisions without being explicitly programmed. Rather than relying on fixed instructions, machine learning algorithms analyze vast amounts of data to identify meaningful patterns and predict outcomes.
Types of learning
Machine learning can be categorized into three main types based on the way the model learns from data:
Supervised learning: Uses labeled data to train models, making predictions or decisions based on examples (e.g., predicting mental health scores based on questionnaire responses).
Unsupervised learning: Finds patterns or structures in unlabeled data (e.g., clustering individuals based on similar traits or behaviors).
Reinforcement learning: Involves an agent interacting with an environment, learning through trial and error with feedback from its actions.
In this course, we will focus on the first two types of learning. If you are interested in reinforcement learning, you can find a nice introduction here.
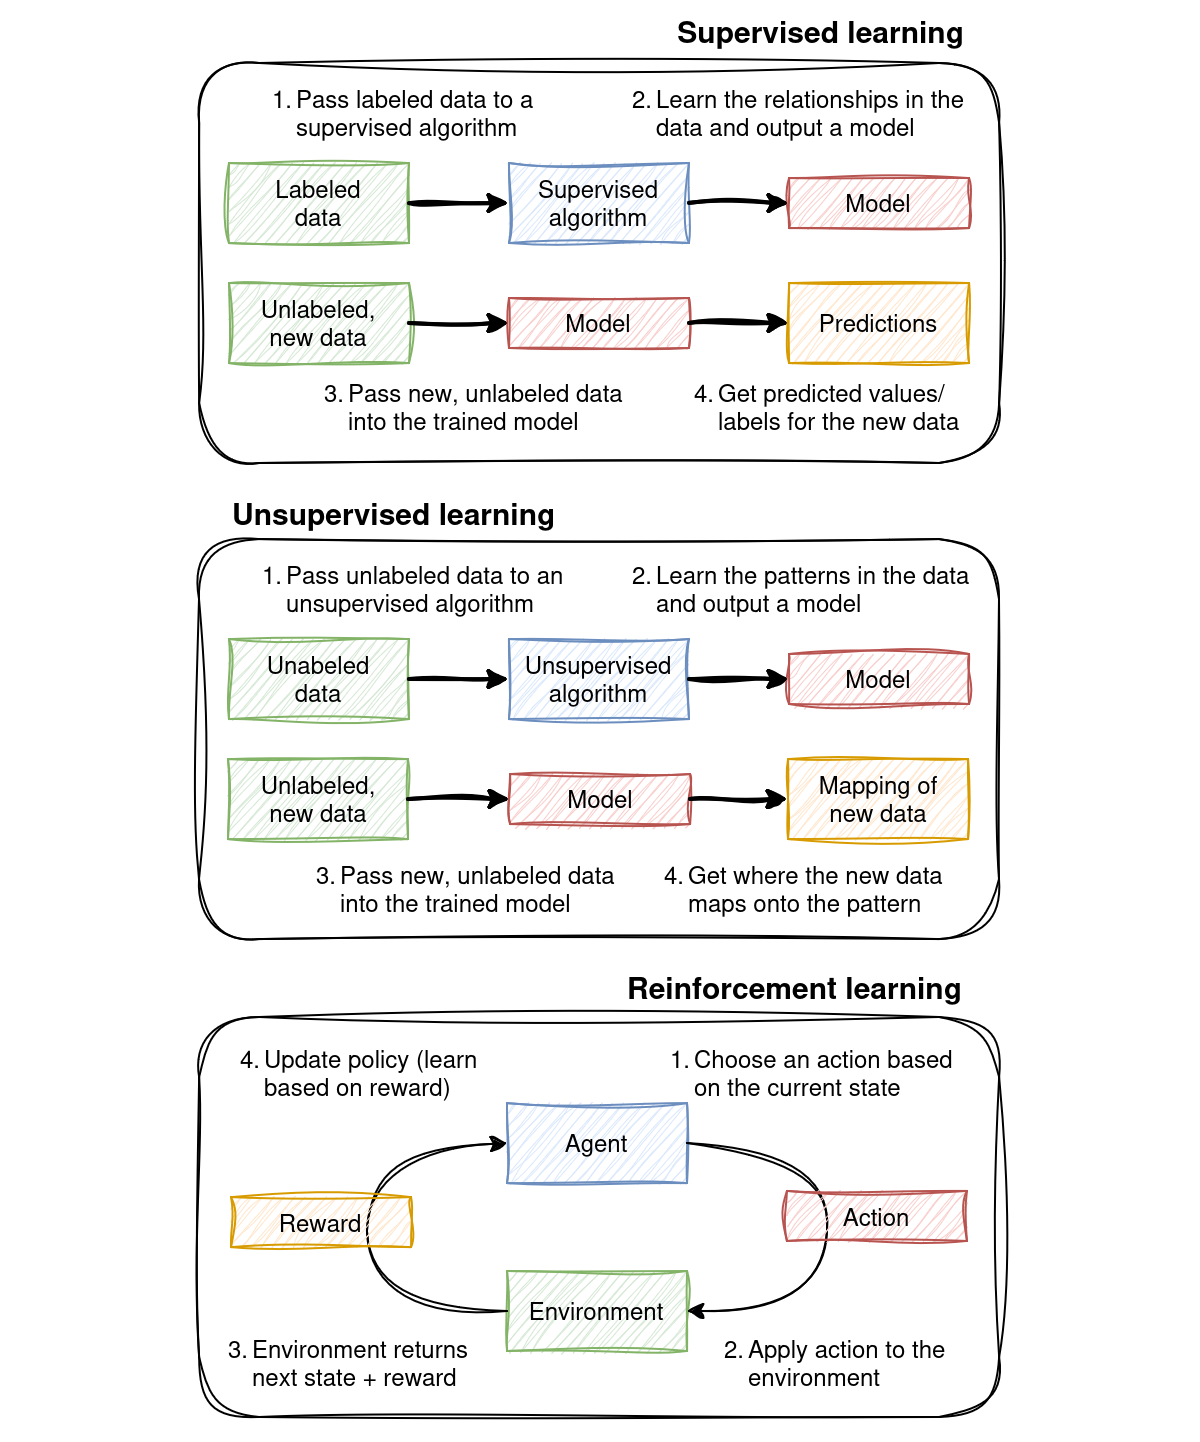
Figure 1:Three main types of machine learning: supervised, unsupervised, and reinforcement learning.
Classes of algorithms
In addition to the type of learning, algorithms can also be categorized based on the type of data they deal with. In supervised learning, this is the type of the outcome we want to predict. In unsupervised learning, there is no outcome, so it is the type of structure we are looking for: discrete groups (clustering) or continuous underlying dimensions (dimensionality reduction):
| Type of data | Supervised learning (labeled outcomes) | Unsupervised learning (no labeled outcomes) |
|---|---|---|
| Qualitative (categorical) | Classification | Clustering |
| Quantitative (numerical) | Regression | Dimensionality reduction |
Almost every chapter of this book fills in one cell of this table. If you ever lose track of where a method belongs, come back here.
Assessing performance
Assessing the performance of a machine learning model is crucial to ensure its accuracy and applicability. Important evaluation metrics for this are:
Mean Squared Error (MSE): Measures the average squared difference between predicted and actual values (regression tasks).
Misclassification error: Describes the proportion of incorrectly predicted class assignments (classification tasks).
There are many more performance metrics (some of which you might already know), such as the Root Mean Squared Error (RMSE), R-squared (R²), accuracy, or precision and recall, which can be derived from a confusion matrix. You will get to know some of them in the following weeks.
Importantly, we usually do not care how well a model describes the data it was trained on (the training error), but how well it predicts new, unseen data (the test error). These two can be very different, as you will see in the next session on the bias-variance tradeoff.
Techniques such as cross-validation help to estimate this test error. Cross-validation repeatedly splits the dataset into training and testing subsets, so that the model is always evaluated on data it has not seen during training. This does not prevent overfitting by itself, but it reveals it and helps us choose models that generalize well. We will explore this topic in the 🎲 Resampling Strategies session.